Mind-to-Face
Neural-Driven Photorealistic Avatar Synthesis via EEG Decoding
Abstract
Current expressive avatar systems rely heavily on visual cues, failing when faces are occluded or when emotions remain internal. We present Mind-to-Face, the first framework that decodes non-invasive electroencephalogram (EEG) signals directly into high-fidelity facial expressions. We build a dual-modality recording setup to obtain synchronized EEG and multi-view facial video during emotion-eliciting stimuli, enabling precise supervision for neural-to-visual learning. Our model uses a CNN-Transformer encoder to map EEG signals into dense 3D position maps, capable of sampling over 65k vertices, capturing fine-scale geometry and subtle emotional dynamics, and renders them through a modified 3D Gaussian Splatting pipeline for photorealistic, view-consistent results. Through extensive evaluation, we show that EEG alone can reliably predict dynamic, subject-specific facial expressions, including subtle emotional responses, demonstrating that neural signals contain far richer affective and geometric information than previously assumed. Mind-to-Face establishes a new paradigm for neural-driven avatars, enabling personalized, emotion-aware telepresence and cognitive interaction in immersive environments.
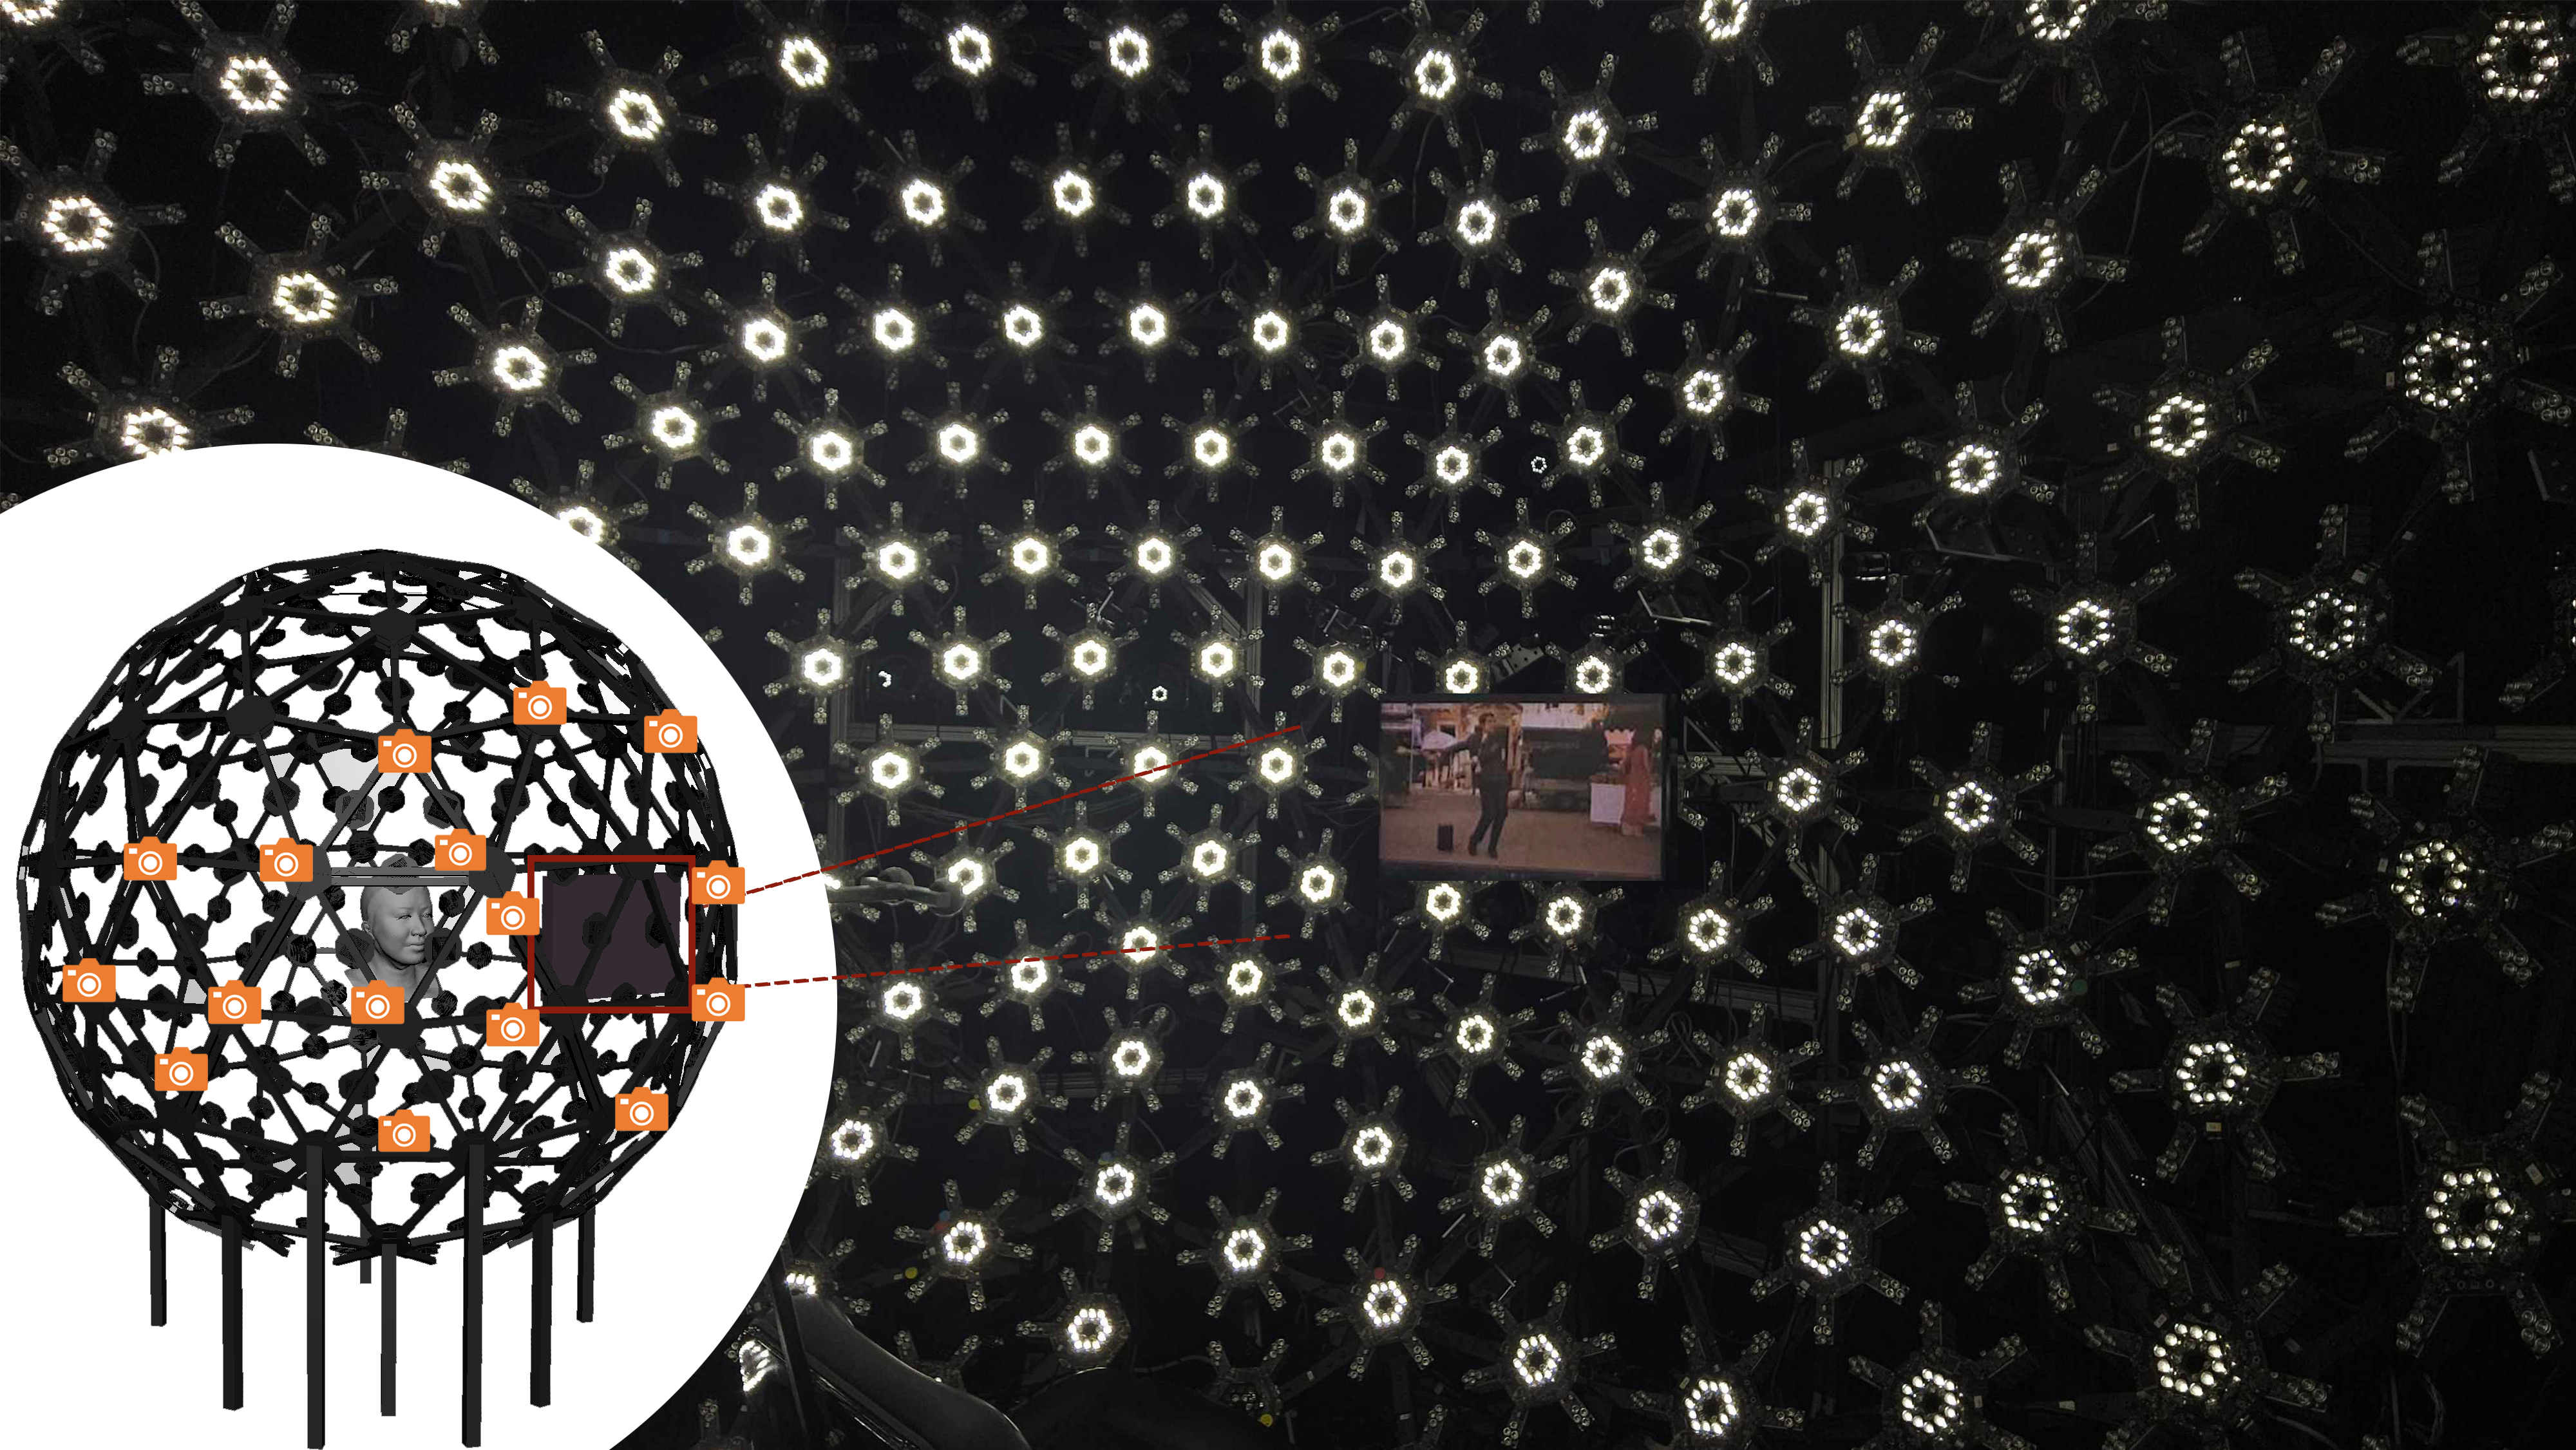
Our Capture System. The monitor plays emotion-eliciting videos to the subject, while the EEG headset records brain signals and the multi-view camera array captures facial expressions.
Our Model Architecture: Our system decodes raw EEG signals into dense 3D position maps that are rendered into photorealistic avatars.
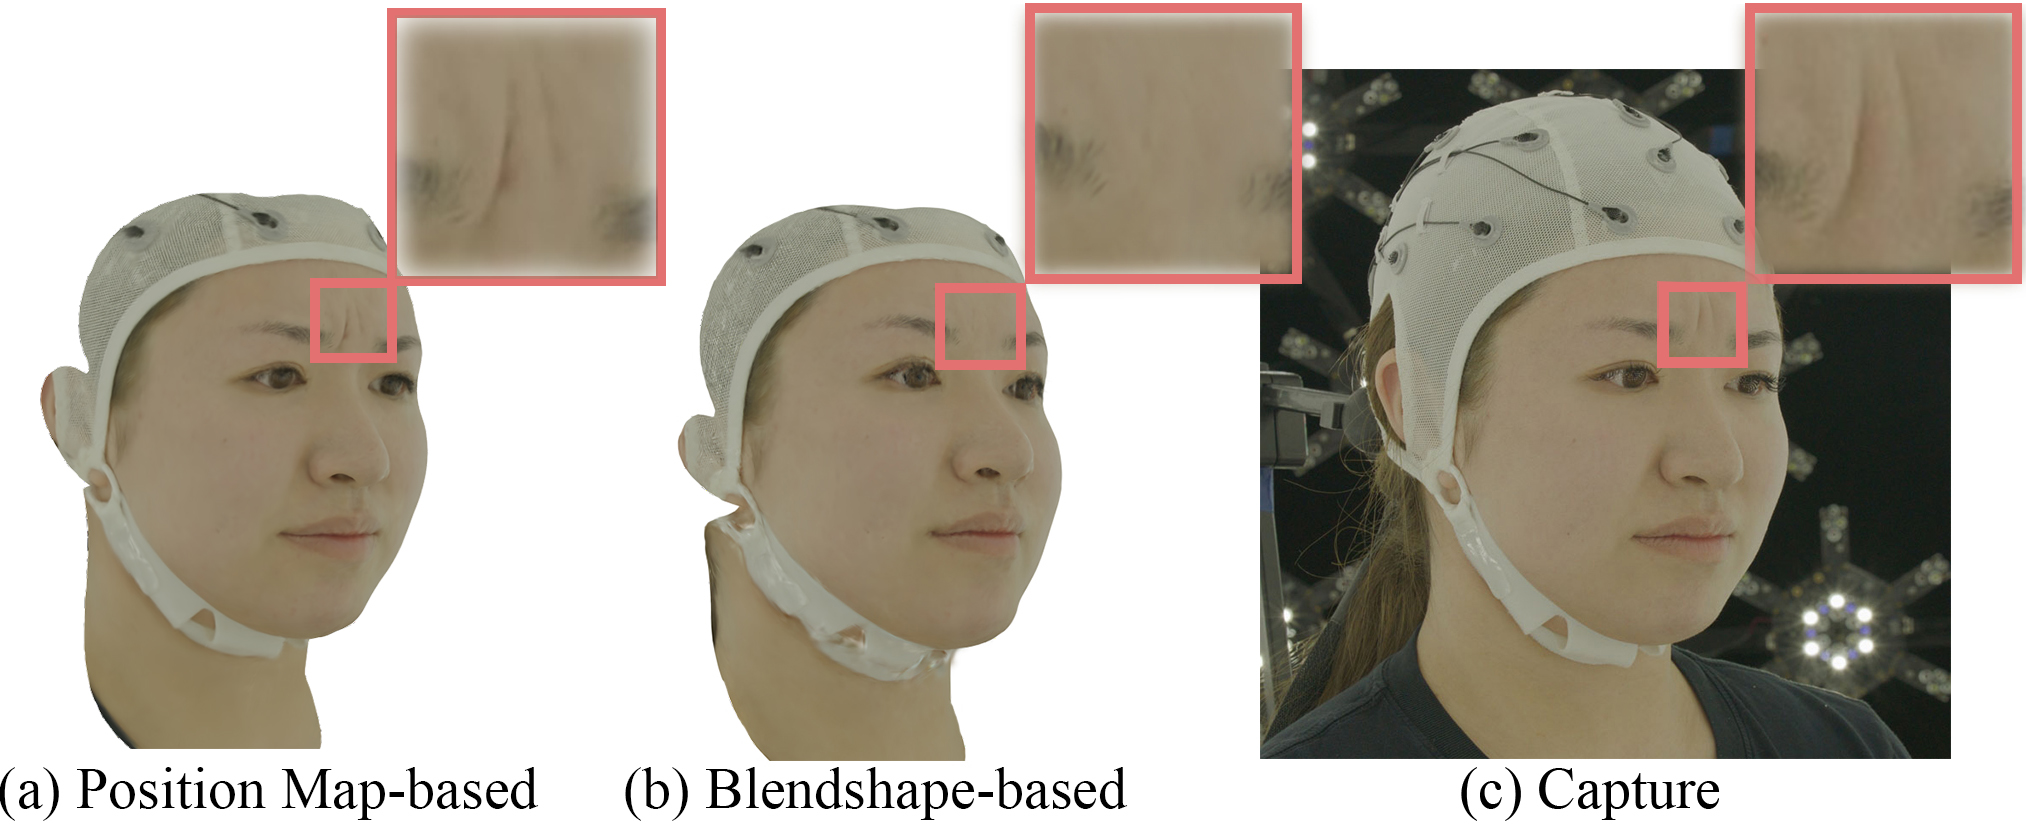
Comparison of Our Position-Map-Based Avatar Rendering with Conventional Blendshape-Based Method.
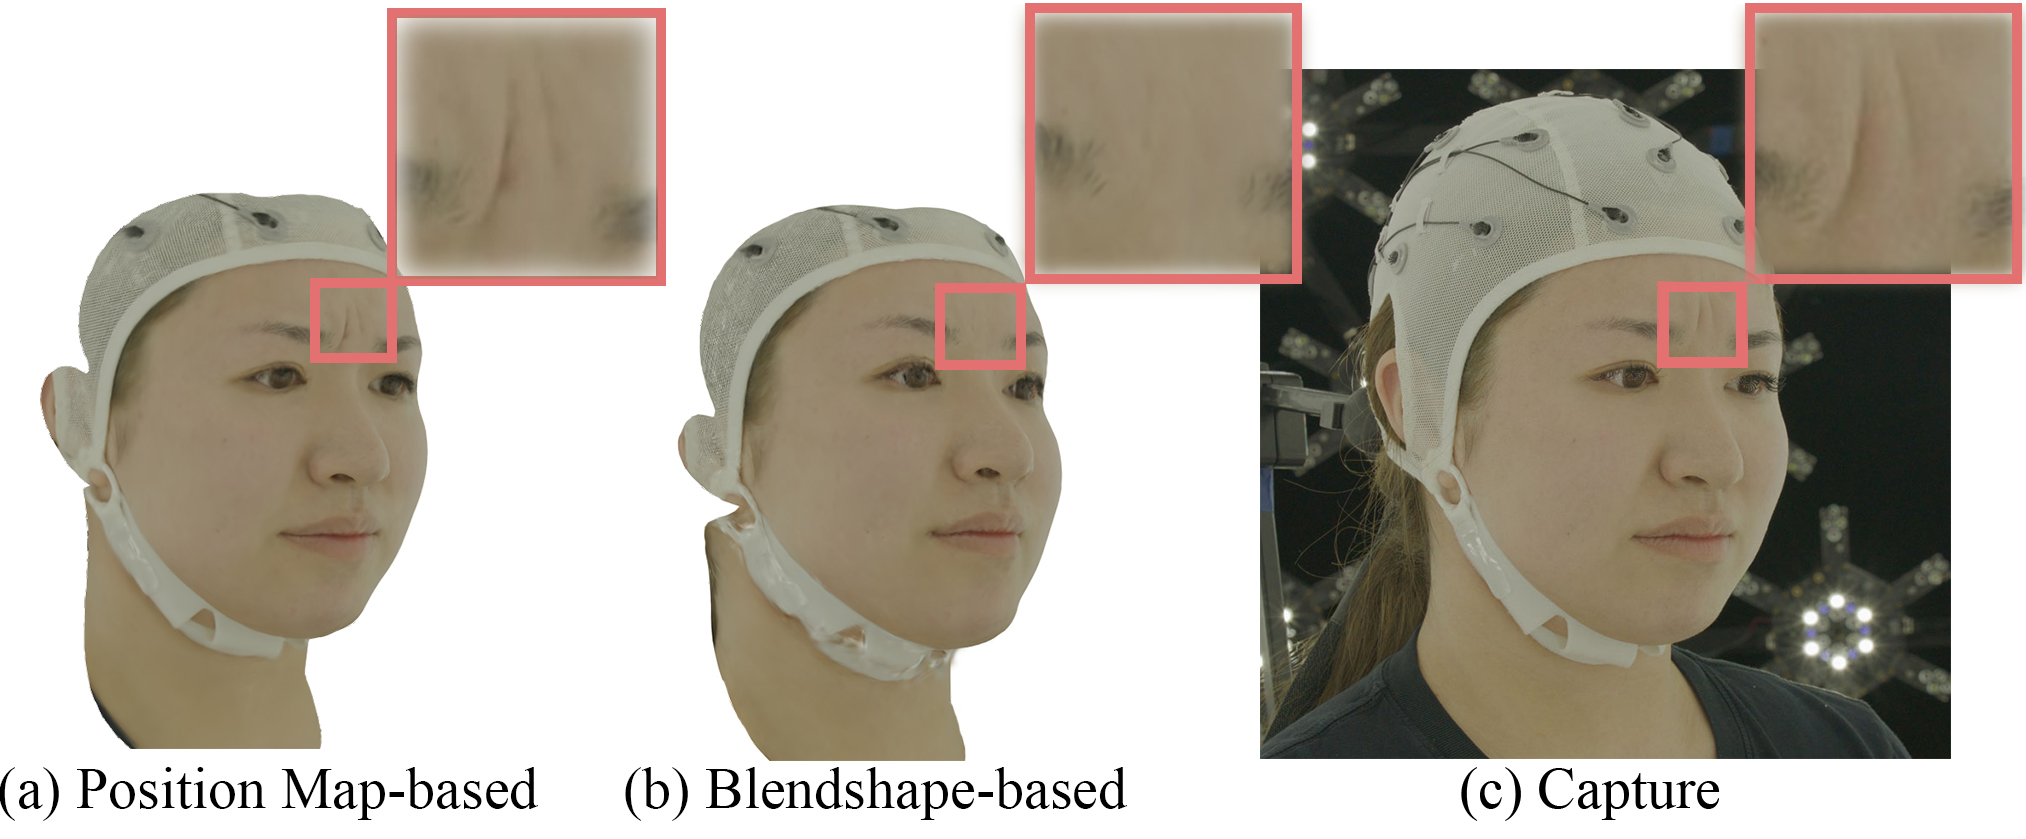
Position-Map-Based Avatar Renderings show more nuanced facial expressions compared to Blendshape-Based Renderings.
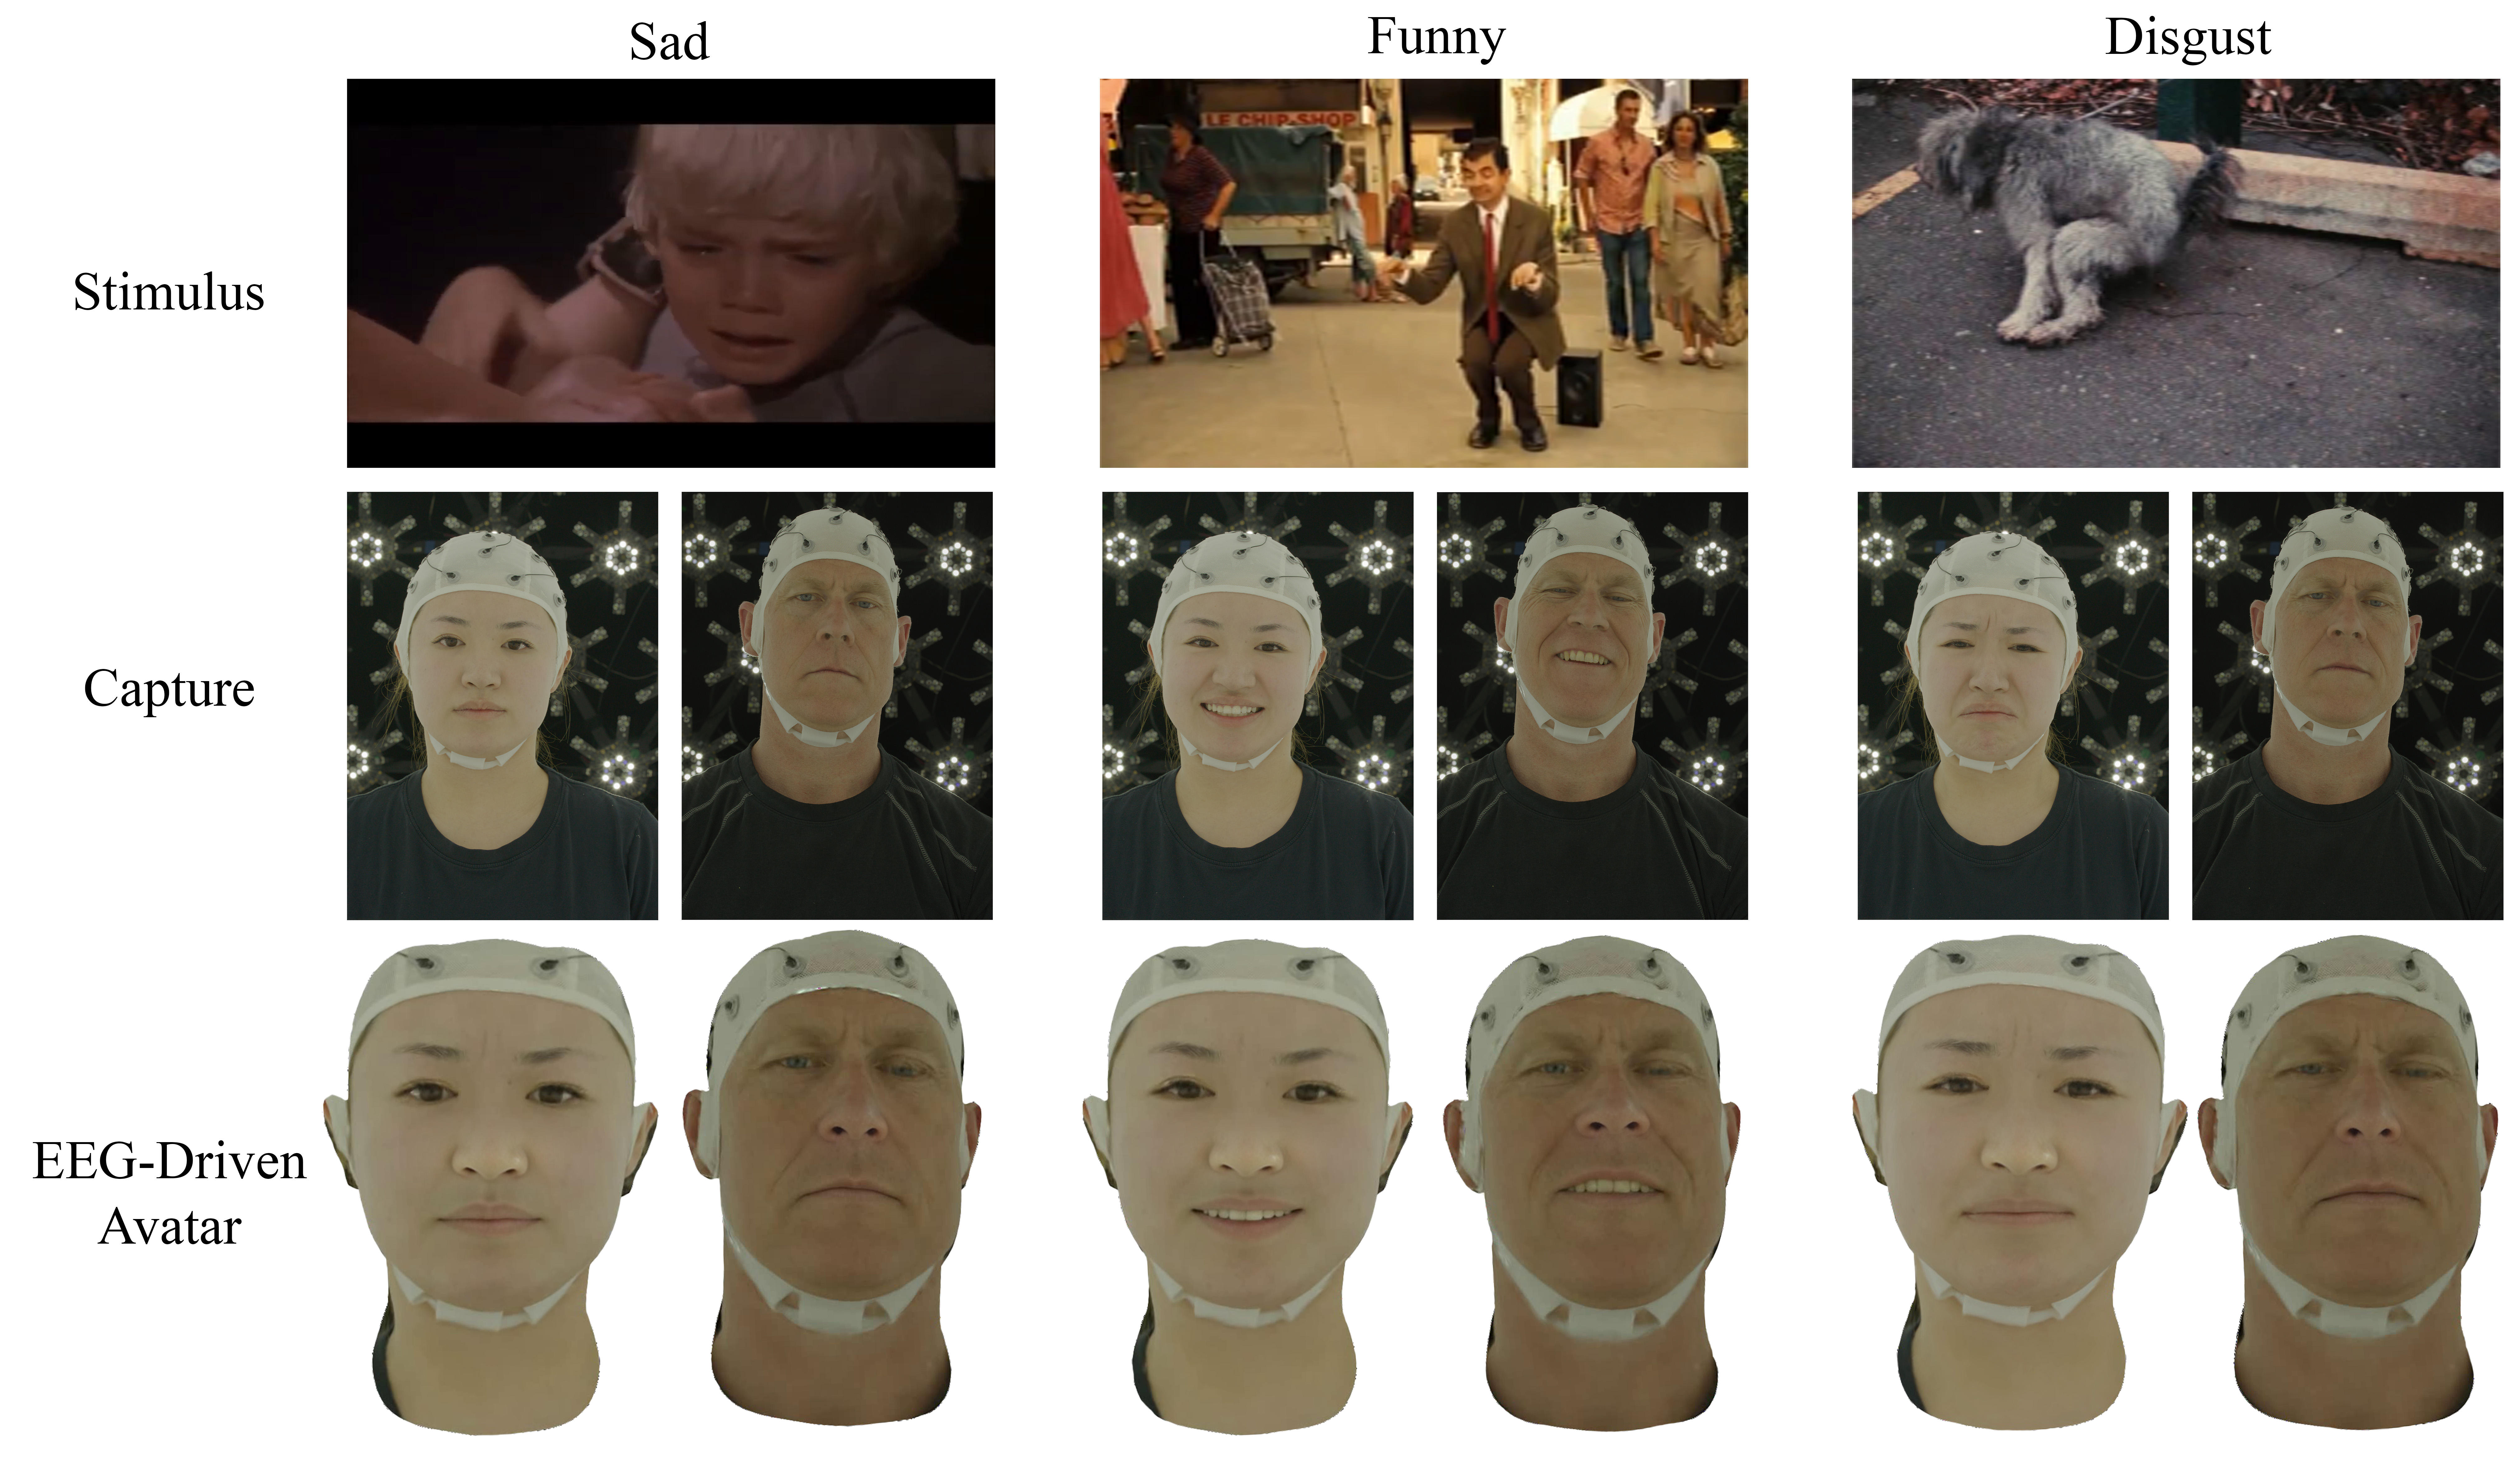
Qualitative Results.
BibTeX
@inproceedings{10.1007/978-3-032-37152-2_17,
  author    = {Xiong, Haolin
               and Fu, Tianwen
               and Prasad, Pratusha Bhuvana
               and Cai, Yunxuan
               and Teng, Wenbin
               and Chen, Haiwei
               and Xiao, Hanyuan
               and Zhao, Yajie},
  editor    = {Favaro, Paolo
               and Kukelova, Zuzana
               and Maki, Atsuto
               and Rohrbach, Anna
               and Schindler, Konrad
               and Tombari, Federico},
  title     = {Mind-to-Face: Neural-Driven Photorealistic Avatar Synthesis via EEG Decoding},
  booktitle = {Computer Vision -- ECCV 2026},
  year      = {2026},
  publisher = {Springer Nature Switzerland},
  address   = {Cham},
  pages     = {300--318},
  abstract  = {Current expressive avatar systems rely heavily on visual cues and often fail when faces are occluded or emotions remain internal. We present Mind-to-Face, the first framework to decode non-invasive electroencephalogram (EEG) signals directly into high-fidelity facial expressions. We build a dual-modality recording setup that captures synchronized EEG and multi-view facial video during emotion-eliciting stimuli, providing precise supervision for neural-to-visual learning. Our model uses a CNN-Transformer encoder to map EEG signals into dense 3D position maps that sample over 65k vertices, capturing fine-scale geometry and subtle emotional dynamics, and renders them through a modified 3D Gaussian Splatting pipeline for photorealistic, view-consistent results. Extensive evaluations show that EEG alone can reliably predict dynamic, subject-specific facial expressions, including subtle emotional responses, demonstrating that neural signals contain far richer affective and geometric information than previously assumed. Mind-to-Face establishes a new paradigm for neural-driven avatars, enabling personalized, emotion-aware telepresence and cognitive interaction in immersive environments.},
  isbn      = {978-3-032-37152-2}
}